Implementing AI for e-commerce delivers tangible business value only when built upon clean data pipelines, decoupled application architecture, and low-latency synchronization between the product catalog and inference models. Integrating artificial intelligence into an online storefront extends far beyond dropping in a generic support chatbot; it requires deep engineering connections between user behavioral events, inventory records, and dynamic pricing engines. This guide breaks down the core architectural layers required for e-commerce artificial intelligence, analyzes semantic retrieval infrastructure, and addresses common system bottlenecks when deploying machine learning at scale.
Artificial intelligence in e-commerce refers to the ecosystem of computational models, machine learning algorithms, and real-time streaming pipelines that process customer telemetry and transaction history to personalize catalog navigation, search ranking, and dynamic pricing per user.
Core Architecture Layers of AI for E-Commerce
Successfully embedding machine learning into a digital store demands strict separation between the presentation tier, business logic, and analytical processing. Implementations frequently degrade when development teams attempt to run compute-intensive database queries or unbuffered large language model calls directly against primary production databases, triggering significant latency spikes that depress conversion rates.
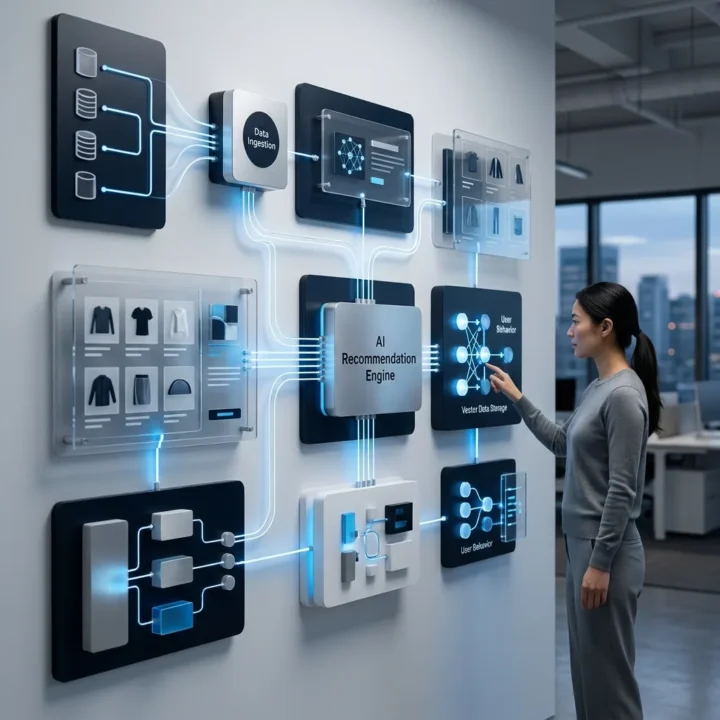
A scalable architecture relies on four decoupled layers:
- Event Ingestion Layer: Captures client-side and server-side user interactions—product views, searches, cart additions, dwell time, and scroll depth. These events stream asynchronously into an ingestion queue to ensure zero blocking on the main thread.
- Data Pipeline and Storage Layer: Unifies raw event streams through schema validation and stores processed representations in analytical warehouses and vector databases. This stage forms the foundation for AI and LLM development utilizing contextual data retrieval.
- Inference and Scoring Engine: Executes real-time and scheduled batch models to predict shopping intent, calculate cart abandonment probabilities, and generate personalized product ranks.
- API and Edge Delivery Tier: Surfaces inference outputs to client frontends via low-overhead REST API endpoints backed by edge caching layers.
This decoupled design integrates cleanly with modern e-commerce engineering architectures, such as headless and composable commerce, keeping frontend performance isolated from backend analytical computing.
| Architecture Component | Recommended Technology | Primary Responsibility |
|---|---|---|
| Event Ingestion | Apache Kafka or AWS Kinesis | Asynchronous streaming of high-volume user interactions without page lag |
| Vector Database | Pinecone, Qdrant, or pgvector | Semantic indexing, multi-dimensional similarity queries, and context retrieval |
| Recommendation Engine | Custom collaborative filtering or graph neural networks | Generating personalized cross-sell and complementary product rankings |
| Edge Delivery Endpoint | Cloudflare Workers or AWS Lambda@Edge | Serving cached inference recommendations in under 50 milliseconds |
Semantic Search and AI-Powered Recommendation Engines
Traditional keyword-based e-commerce search relies strictly on lexical matching. When a shopper submits a query like "lightweight dress for outdoor summer wedding," an SQL pattern match or basic inverted index often yields zero results if those exact words are not indexed in the title or metadata.
Semantic search systems solve this by converting both product catalogs and search queries into mathematical coordinates using vector embeddings. Leveraging retrieval frameworks like RAG (Retrieval-Augmented Generation), the system evaluates cosine similarity between the shopper's conceptual intent and catalog vectors. Detailed technical patterns for autonomous commerce agents are explored in our guide on adapting e-commerce for AI agents. To review official specifications on vector indexing and hybrid search, consult the Elasticsearch Semantic Search Documentation.
Deploying semantic discovery requires tight coordination with product design teams. Recommendation components must blend into the purchase funnel without delaying initial Largest Contentful Paint (LCP) or disrupting the visual hierarchy of the product detail page, ensuring recommendations reduce friction rather than introducing cognitive fatigue.
Dynamic Catalog Optimization with Natural Language Processing
Managing enterprise catalogs with tens of thousands of dynamic SKUs presents chronic data normalization challenges. Modern Natural Language Processing (NLP) models streamline catalog hygiene by extracting attributes directly from unstructured vendor feeds:
- Automated Taxonomy Categorization: Extracting attributes such as material, cut, sizing, and aesthetic style from unstructured text and imagery to populate structured database fields.
- Context-Aware Description Synthesis: Generating tailored product copy variants targeting specific buyer segments while maintaining unified brand voice guidelines.
- Data Integrity Auditing: Identifying missing metadata, invalid specifications, or mismatches between imagery and written specifications before SKUs go live.
System Integration and Cross-Platform Data Synchronization
Predictive models cannot function effectively within an isolated data silo. To generate accurate product recommendations, models must receive continuous state updates from enterprise resource planning (ERP), customer relationship management (CRM), and warehouse management systems (WMS). A recommendation model that suggests items out of stock in a shopper's regional fulfillment center generates immediate operational friction.
Preventing data drift requires an event-driven integration architecture driven by webhooks and asynchronous message brokers. When inventory levels decrement in the ERP, an update event publishes to the vector database to suppress out-of-stock items from real-time recommendation carousels within milliseconds.
Standards for client-side compute performance, security, and user data containment are outlined in the W3C Machine Learning for the Web community specifications, highlighting edge calculation strategies that restrict transmitting personally identifiable information to external APIs.
Common Pitfalls in AI Implementations for E-Commerce
Production failures in retail machine learning rarely stem from algorithm limitations; they almost always trace back to runtime architecture errors:
- Synchronous LLM Requests on Page Load: Blocking initial server rendering while awaiting an external model generation causes catastrophic increases in Time to First Byte (TTFB). Recommendations must be precomputed or fetched asynchronously post-render.
- Data Leakage and Security Vulnerabilities: Sending un-sanitized customer transaction logs or proprietary margin data to third-party model endpoints creates severe regulatory and compliance liabilities.
- Missing Graceful Fallbacks: High-availability systems must define explicit fallback states. If the vector index or inference service exceeds a 100ms timeout budget, the interface must immediately fall back to cached popularity baselines.
- Unmonitored Model Drift: Consumer purchase behaviors fluctuate rapidly across seasonal shifts and promotions. Recommendation models that lack continuous validation pipelines against ground-truth conversion telemetry degrade within weeks.
If your organization is scaling its online platform, optimizing search infrastructure, or planning an end-to-end data pipeline, contact our engineering team to evaluate the architectural foundation of your digital storefront.
Common questions
What is AI for e-commerce and how does it differ from traditional search plugins?
AI for e-commerce encompasses mathematical models and machine learning pipelines that analyze real-time user behavior, infer intent, and deliver contextual personalization. Unlike traditional search plugins that depend on hardcoded rules and exact lexical keyword matching, artificial intelligence evaluates semantic relationships, behavioral signals, and multi-dimensional vector similarities to display relevant items even when exact search terms do not match catalog attributes.
How does integrating AI models affect page load speed?
Integrating AI models degrades page load speed if external inference APIs are invoked synchronously during initial page generation. To maintain optimal Core Web Vitals, engineering teams separate analytical computation from the rendering thread, cache computed recommendations at the network edge, and inject personalized assets asynchronously via client-side endpoints only after critical visual components have fully loaded.
Does an online store need its own proprietary LLM or an existing cloud API?
Online stores rarely require training a custom foundation large language model from scratch. The most cost-effective and performant architecture uses managed foundation models accessed through cloud APIs or self-hosted open-source models, augmented by the merchant's proprietary catalog data using vector databases and Retrieval-Augmented Generation workflows.
What data is required to run an effective product recommendation engine?
An effective product recommendation engine requires three primary datasets: structured product catalog metadata including taxonomy and variants, historical customer transaction records showing past purchase affinities, and real-time behavioral event telemetry including clicks, category views, add-to-cart actions, and session dwell times.
Share this article
Want us to take a look?
Tell us what you are building and we will come back within one business day.